Inference engineers, AI infrastructure architects, and platform teams evaluating: NVIDIA Nemotron 3 Ultra inference, NVIDIA H200 GPU infrastructure, NVIDIA AIPerf benchmarking, vLLM KV cache offloading, MemKV context memory, KV cache tiering, NVMe over RDMA for AI inference, Hybrid Mamba-Transformer models, Large-scale agentic AI inference

Key Benchmark Results:
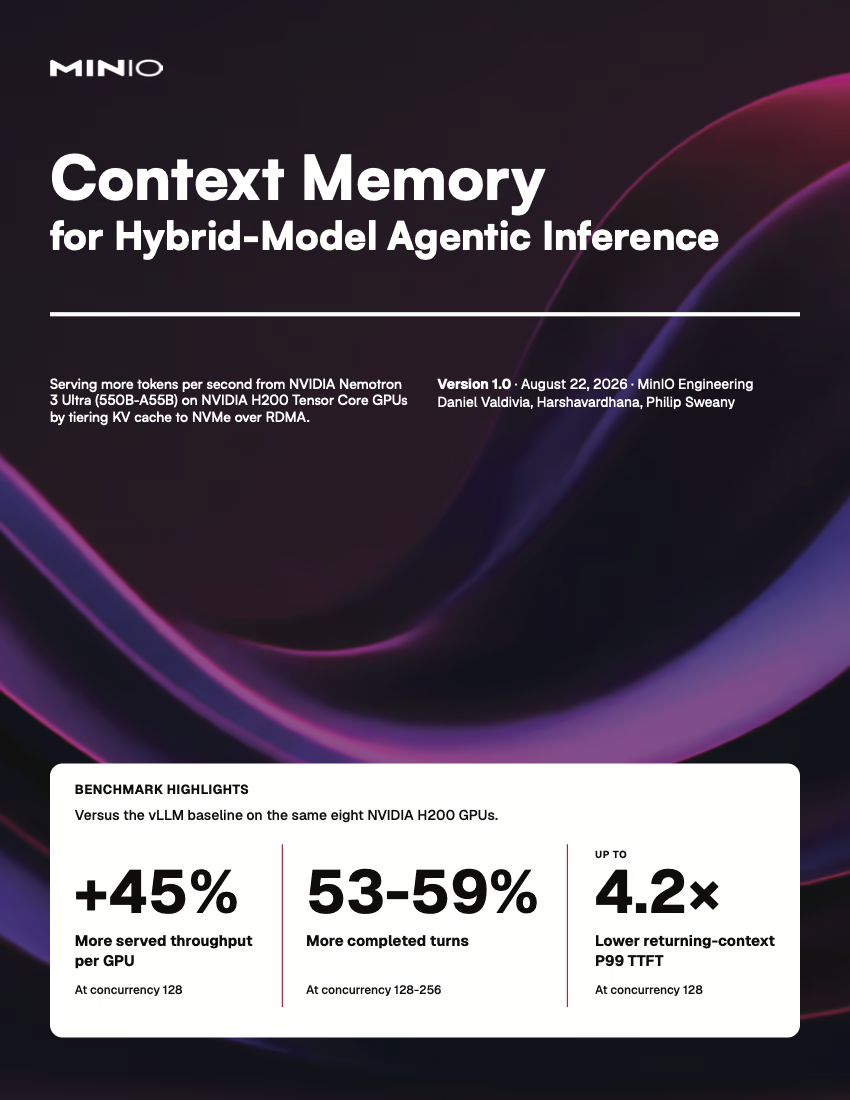
45% more served throughput per GPU at concurrency 128: With MemKV backing vLLM native KV offloading, the benchmark reached 7,673 served tokens/s/GPU compared with 5,286 tokens/s/GPU for the vLLM baseline at concurrency 128.
53–59% more completed agent turns: The MemKV tier completed 815 turns versus 531 at concurrency 128 and 842 versus 529 at concurrency 256 in identical 12-minute benchmark windows.
Up to 4.2× lower returning-context P99 TTFT: At concurrency 128, returning-context P99 time to first token fell from 143.6 seconds with the vLLM baseline to 34.0 seconds with the MemKV hierarchy.
The throughput frontier moved from concurrency 64 to 128: The same eight NVIDIA H200 GPUs supported roughly twice the concurrent agent sessions before throughput began to decline.
What The Benchmark Tests:
The benchmark uses NVIDIA Nemotron 3 Ultra, a 550B-parameter hybrid Mamba-Transformer mixture-of-experts model with approximately 55B active parameters. The model is served with vLLM across eight NVIDIA H200 GPUs using an NVIDIA AIPerf agentic-code workload with 30–60 second human-scale pauses between turns. The MemKV configuration uses two commodity NVMe storage servers connected over dual-rail RoCEv2. Three configurations are compared: vLLM GPU prefix-cache baseline, DRAM-only KV cache, and vLLM native KV offload with DRAM plus MemKV
Why Context Memory Matters For Agentic Inference:
Long-running AI agents continually accumulate context. When active sessions exceed the context that GPU HBM can retain, idle sessions are evicted. When those sessions return, the inference engine must recompute the previous context before generating the next response. In this benchmark, that recompute tax causes returning-context latency to jump sharply once the system crosses its memory-capacity threshold. The vLLM baseline's returning-turn P99 TTFT rises from 5.2 seconds at concurrency 64 to 78.3 seconds at concurrency 96. MemKV extends context memory beyond GPU HBM and DRAM using NVMe over RDMA, allowing previously generated KV cache to be restored instead of recomputed.
Hybrid Mamba-Transformer KV Cache Requirements:
Hybrid models such as NVIDIA Nemotron 3 Ultra can appear to require relatively little KV cache because only part of the architecture uses conventional attention. However, reusable prefix caching also requires storing the model's recurrent Mamba state. In the tested configuration, enabling prefix caching reduced usable KV capacity from approximately 8.90 million tokens to 1.84 million tokens, a 79% reduction. That is why context-memory capacity can become a constraint for hybrid agentic inference much earlier than attention-head arithmetic alone suggests.