The most expensive computers ever built spend a surprising amount of their time waiting on storage.
The most expensive computers ever built spend a surprising amount of their time waiting on storage.
For the better part of a decade, we have made object storage faster the same way: more drives, more nodes, faster NICs. And it worked, modern object stores saturate 400 GbE links without breaking a sweat. But every one of those bytes still takes the same last hop it took ten years ago: into host memory, through the kernel's TCP stack, copied by CPU cores, and only then handed to the GPU that actually asked for it. The network got two orders of magnitude faster. The last hop didn't change.
MinIO AIStor with NVIDIA GPUDirect® RDMA for S3-Compatible storage changes it. A GET lands directly in GPU memory: the object store writes into VRAM over the RDMA fabric, and the host CPU steps out of the data path entirely. Same S3 API, same buckets, same erasure coding. What disappears is the copy. The data path leverages the NVIDIA cuObject library, which uses RDMA to accelerate the S3 API-based storage protocol rather than replace it.
In this blog post we are going to look at why that last hop has quietly become the tax on every AI workload, training, checkpointing, and inference cold starts, and what our measurements say happens when you remove it.
The Problem Wears Three Disguises
Ask three teams what their storage problem is and you will get three different answers. They are the same problem.
Training clusters fail, constantly, and checkpoints are the insurance. Meta reported that during a 54-day snapshot of Llama 3 405B pre-training on up to 16K NVIDIA H100 Tensor Core GPUs, they experienced 466 job interruptions, about one every three hours, with roughly 78% of the unexpected ones attributed to confirmed or suspected hardware issues. And that is not a Llama-sized anomaly: in a separate study of 11 months and over 150 million GPU-hours on NVIDIA A100 Tensor Core GPUs across their research clusters, Meta measured the mean-time-to-failure of a 1,024-GPU job at 7.9 hours, and projected 1.8 hours at 16,384 GPUs. At 131,072 GPUs the projection is 14 minutes.
The insurance premium is the checkpoint. Meta's reliability study notes that hourly checkpointing is typical for larger jobs on their clusters, which means an average of half an hour of lost work every time the job dies. Their own stated goal in the Llama 3 paper is exactly the one you would guess: "minimize GPU pause time during checkpointing and increase checkpoint frequency to reduce the amount of lost work after a recovery." The obstacle is also the one you would guess: checkpoint writes are "highly bursty" and "saturate the storage fabric for short durations", and that is on a storage fleet Meta describes as sustaining 2 TB/s with 7 TB/s peaks. Facebook's checkpointing team put it even more directly, as far back as 2020: "checkpoint frequency is often bottlenecked by the storage write bandwidth and capacity." ByteDance felt the same pain, their ByteCheckpoint system exists because production checkpoint stalls were bad enough to justify rebuilding the whole pipeline, reducing stalls by an average of 54×.
Inference fleets pay the same tax at startup. The ServerlessLLM work from OSDI '24 identified remote checkpoint download and loading as the dominant cost in serverless LLM inference, and earned a 10–200× latency reduction largely by attacking how weights get into the GPU. Every autoscaling event, every node replacement, every new model version, someone waits while tens of gigabytes of safetensors crawl from storage into VRAM.
And training itself pays it on every batch. Even when your data loader keeps up, the CPU cores it burns to move and copy bytes are cores your training loop wanted for augmentation, tokenization and Python.
Three disguises, one problem: the bytes are in the object store, the tensors need to be in GPU memory, and everything between them runs through the host.
The Host Steps Out
RDMA lets a NIC write into a remote machine's memory without the remote CPU touching the transfer. NVIDIA GPUDirect® RDMA for S3-Compatible storage carries the same principle into the storage path, so the memory being written is GPU memory. NVIDIA documents cuObject as direct data transfer between GPU memory or system memory and S3-compatible object storage over RDMA, with the host CPU out of the transfer. AIStor puts the two together behind the S3 API: the client hands the object store an RDMA descriptor for a buffer in VRAM, and the storage nodes stream the object straight into it over the RDMA fabric.
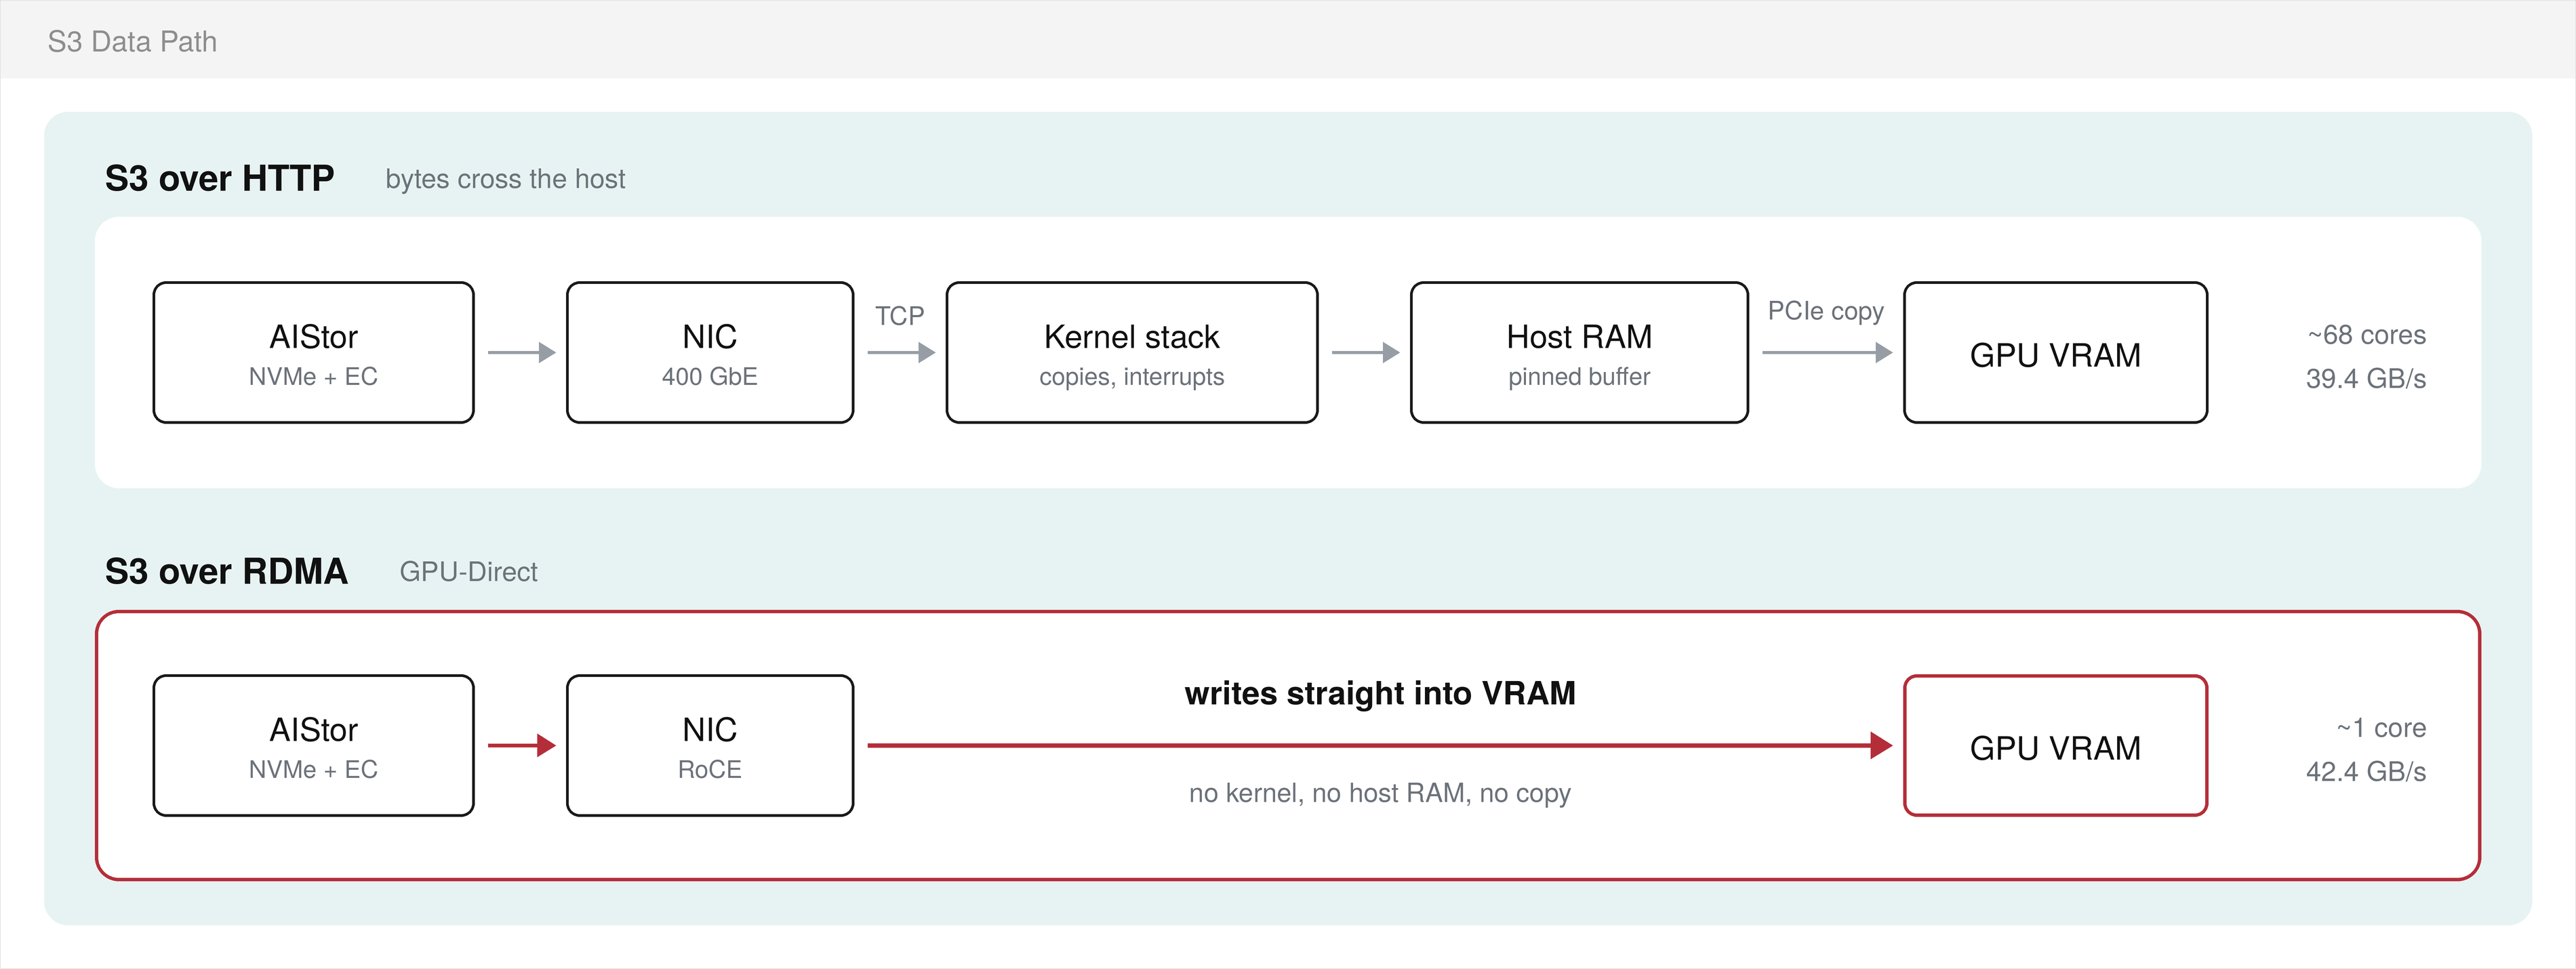
NVIDIA gives the pattern a name and a shape. NVIDIA GPUDirect® RDMA for S3-Compatible storage uses remote direct memory access to accelerate the S3 API-based storage protocol, delivered as client and server libraries that storage partners integrate. NVIDIA documents those libraries as NVIDIA cuObject, GPUDirect Storage for Objects, and the design there splits control from data. Standard S3 GET and PUT requests travel a REST control plane and carry header tags such as x-amz-rdma-token, while the object payload moves on an RDMA data plane, transferred directly between the storage node and GPU or system memory, bypassing the host CPU. The split is the reason nothing above the storage layer has to change. The application plane stays S3. Only the transfer mechanism underneath it moves.
cuObject ships as two libraries. The client library integrates into the GPU application or middleware, intercepts the S3 request, manages the RDMA data sink or source, and is available in the NVIDIA CUDA® Toolkit from release 13.1.1. The server library integrates into the storage partner's object server, which is where AIStor does its part. Transport is Dynamic Connection (DC), which works over InfiniBand and RoCEv2 and does not require pre-establishing a connection between every client and server pair. NVIDIA describes the architecture as open, and is working with partners to standardize it.
Nothing about your bucket changes. The object is still erasure-coded across the same drives; a plain HTTP client still reads it. RDMA is negotiated per request, so the same tenant serves your GPU cluster over RDMA and your dashboards over HTTP at the same time. Portability survives the change as well. The workloads keep calling S3, so they run unmodified on premises and in cloud service provider and neocloud environments.
Here is what removing the last hop measures out to. We published every benchmark, the loaders, and the raw results in minio/rdma-training, and every RDMA figure in it is backed by a server-side RDMA counter delta, so you are never taking the client's word that RDMA actually carried the bytes.
Test configuration. The figures below come from the environment in Figure 1: MinIO AIStor on NVMe with erasure coding, NVIDIA ConnectX®-7 adapters at 400 GbE over RoCEv2 on NVIDIA Spectrum-X™ Ethernet networking, serving a GPU client with 8× NVIDIA H200 Tensor Core GPUs and the NVIDIA cuObject client library. HTTP baselines run on the same fabric. Per-run details are in the raw results in the repo.
Raw delivery into GPU memory. On a single 400 GbE rail, S3 over RDMA sustained 42.4 GB/s into VRAM using 0.95 CPU cores. A heavily tuned HTTP loader on the same fabric reached 39.4 GB/s, using 68.2 cores. Same bandwidth ceiling, 70× the CPU. That ratio is the whole story in one line: at 400 Gb, the bottleneck is not the network, it is the copy. NVIDIA describes the mechanism the same way: RDMA for S3-compatible storage does not use the host CPU for data transfer. On a GPU server, that capacity goes back to work that produces tokens.
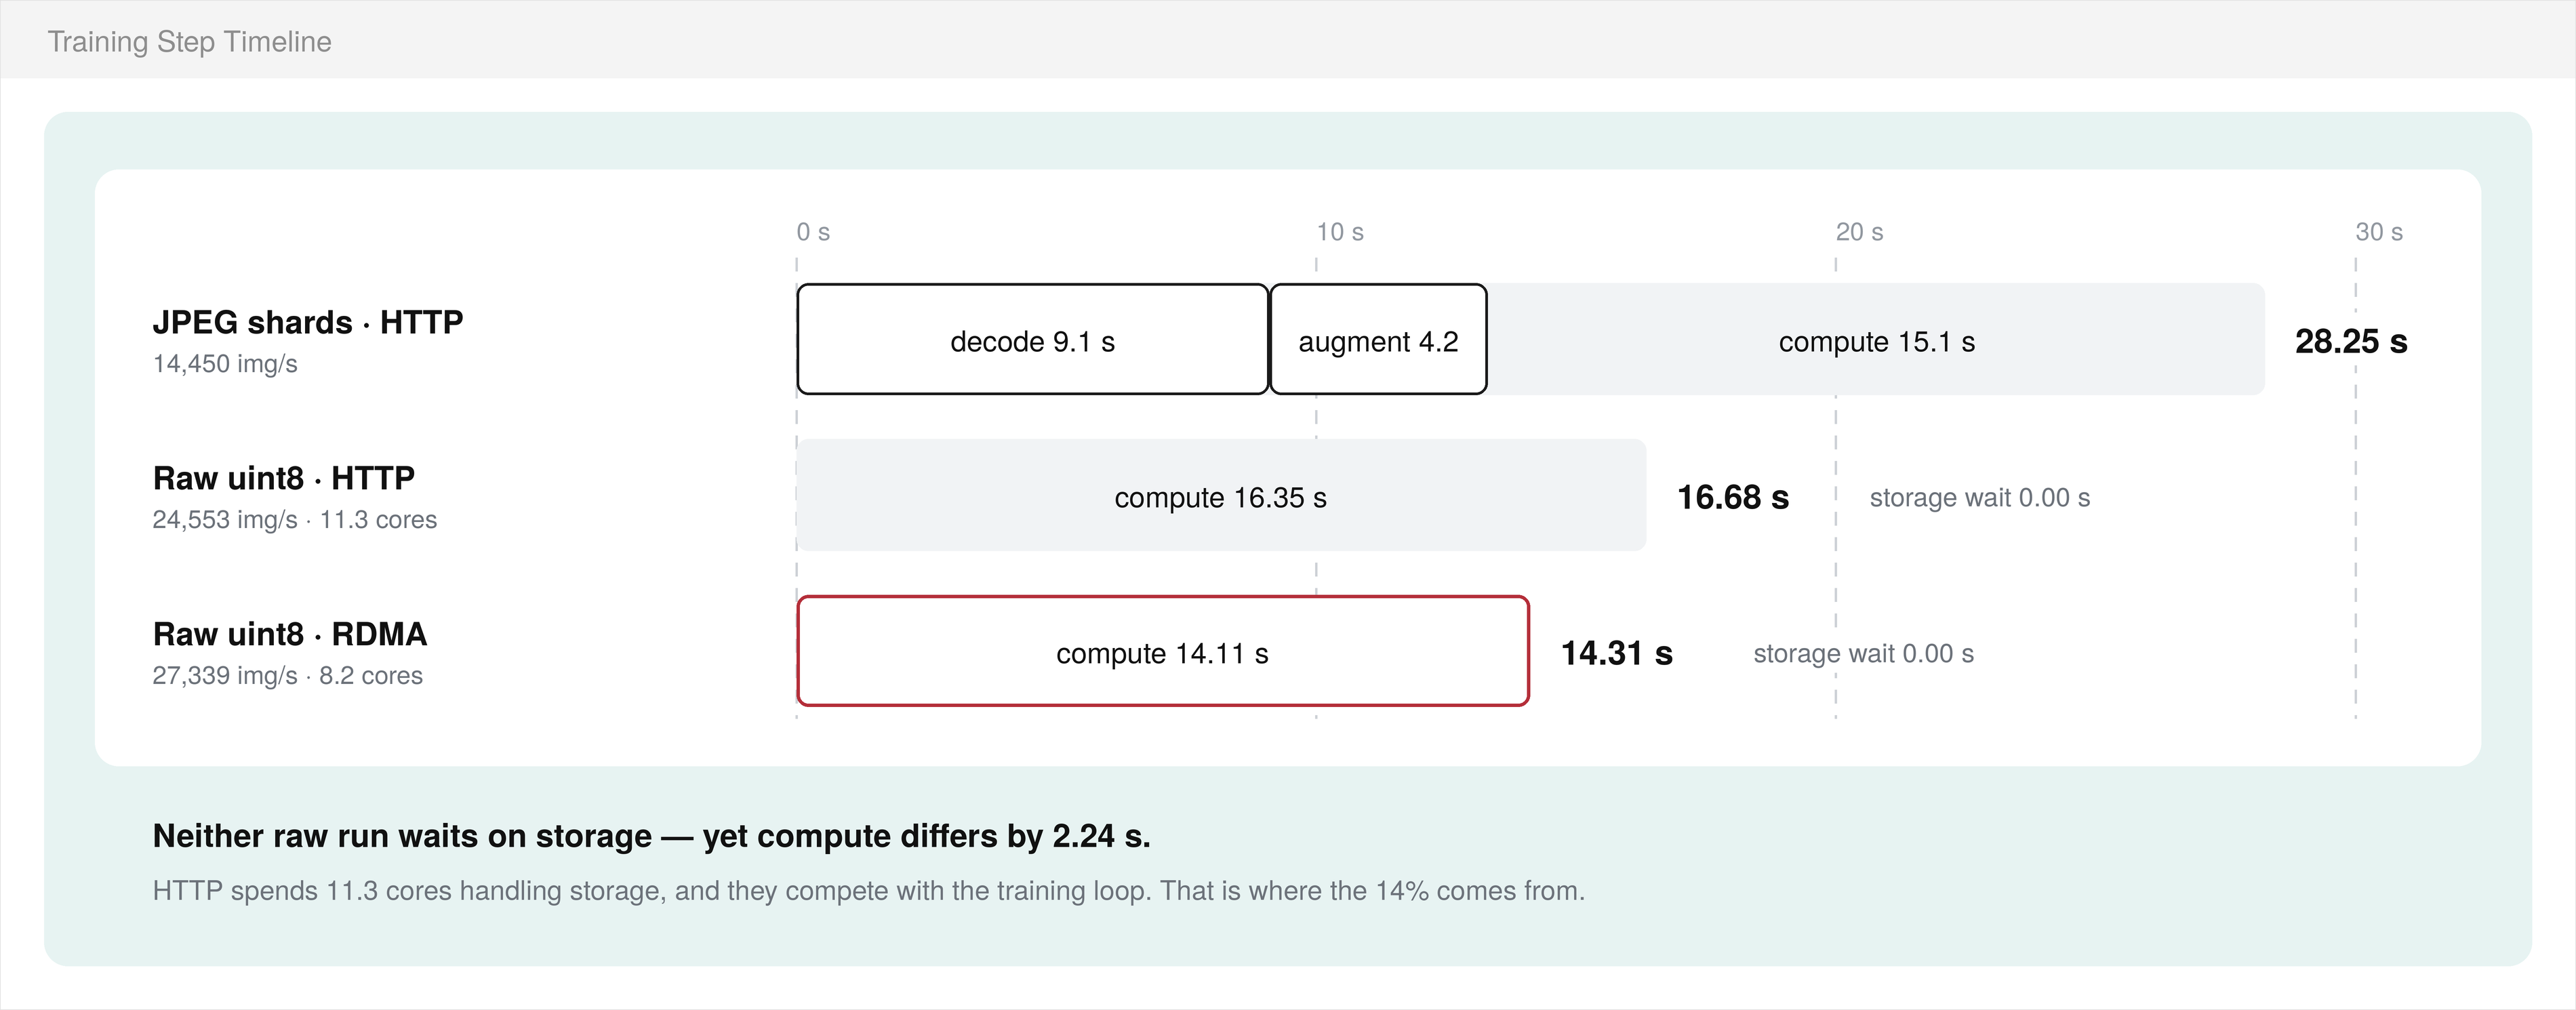
Training. On the 8× NVIDIA H200 client, a ResNet-50 run over GPU-native uint8 shards finished the same 200 batches 14% faster over RDMA than over HTTP, 14.31 s versus 16.68 s, with storage wait at 0.00 s on both transports. The gain is CPU: the HTTP run used 11.3 cores to the RDMA run's 8.2, and the HTTP data path's appetite competes with the training loop itself. The tax shows up even when you never wait on storage.
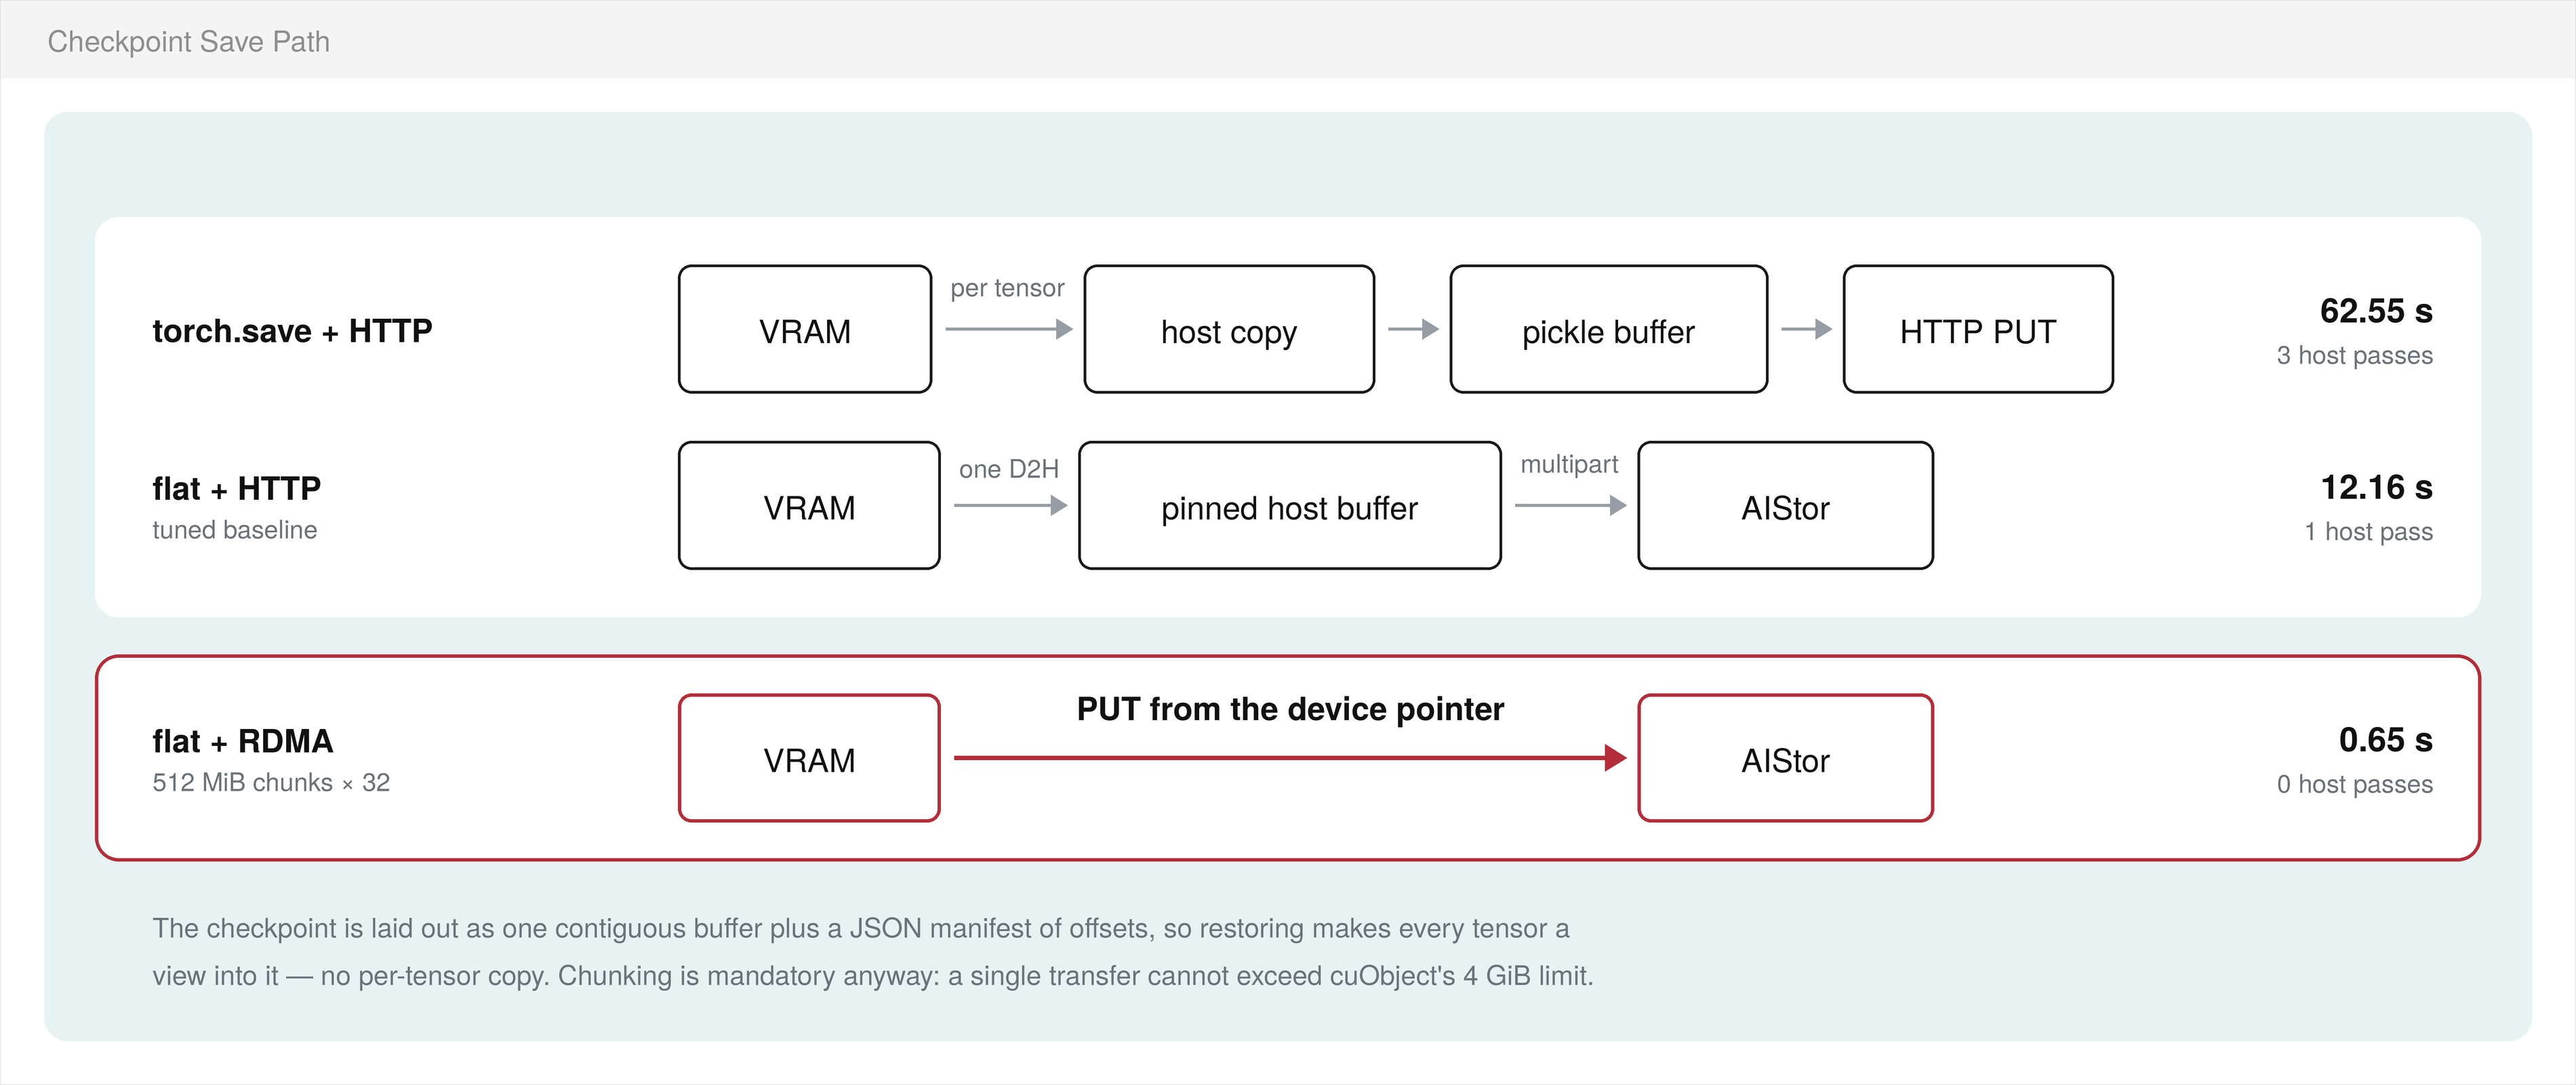
Checkpointing. A 16 GiB checkpoint, written as one flat buffer in 512 MiB chunks straight from the device pointer, lands in 0.65 s over RDMA, against 12.16 s for tuned HTTP and 62.55 s for a plain torch.save. At LLM scale, 112 GiB of sharded state across 8 ranks completes in 4.33 s at 28 GB/s on 3.7 CPU cores, versus 14.42 s and 30.4 cores over HTTP. Go back to Meta's math: if the cost of a checkpoint drops by an order of magnitude, checkpointing more often stops being a trade-off, and the half hour of average lost work shrinks with it. Turning that knob is precisely what their papers say they want.
Cold starts. Llama-3.1-8B's full 16 GB of safetensors weights loaded from AIStor into VRAM in 0.77 s over RDMA, faster than loading the same file from the client's local NVMe with a warm cache (2.29 s), and 40× faster than the download-then-load pattern, pulling the weights to local disk first and then loading them (30.96 s). Qwen3-32B: 65 GB in 3.10 s over RDMA versus 125 s download-then-load. When the model store is faster than the local disk, as it was here, the case for baking weights into images or pre-staging them on every node quietly evaporates.
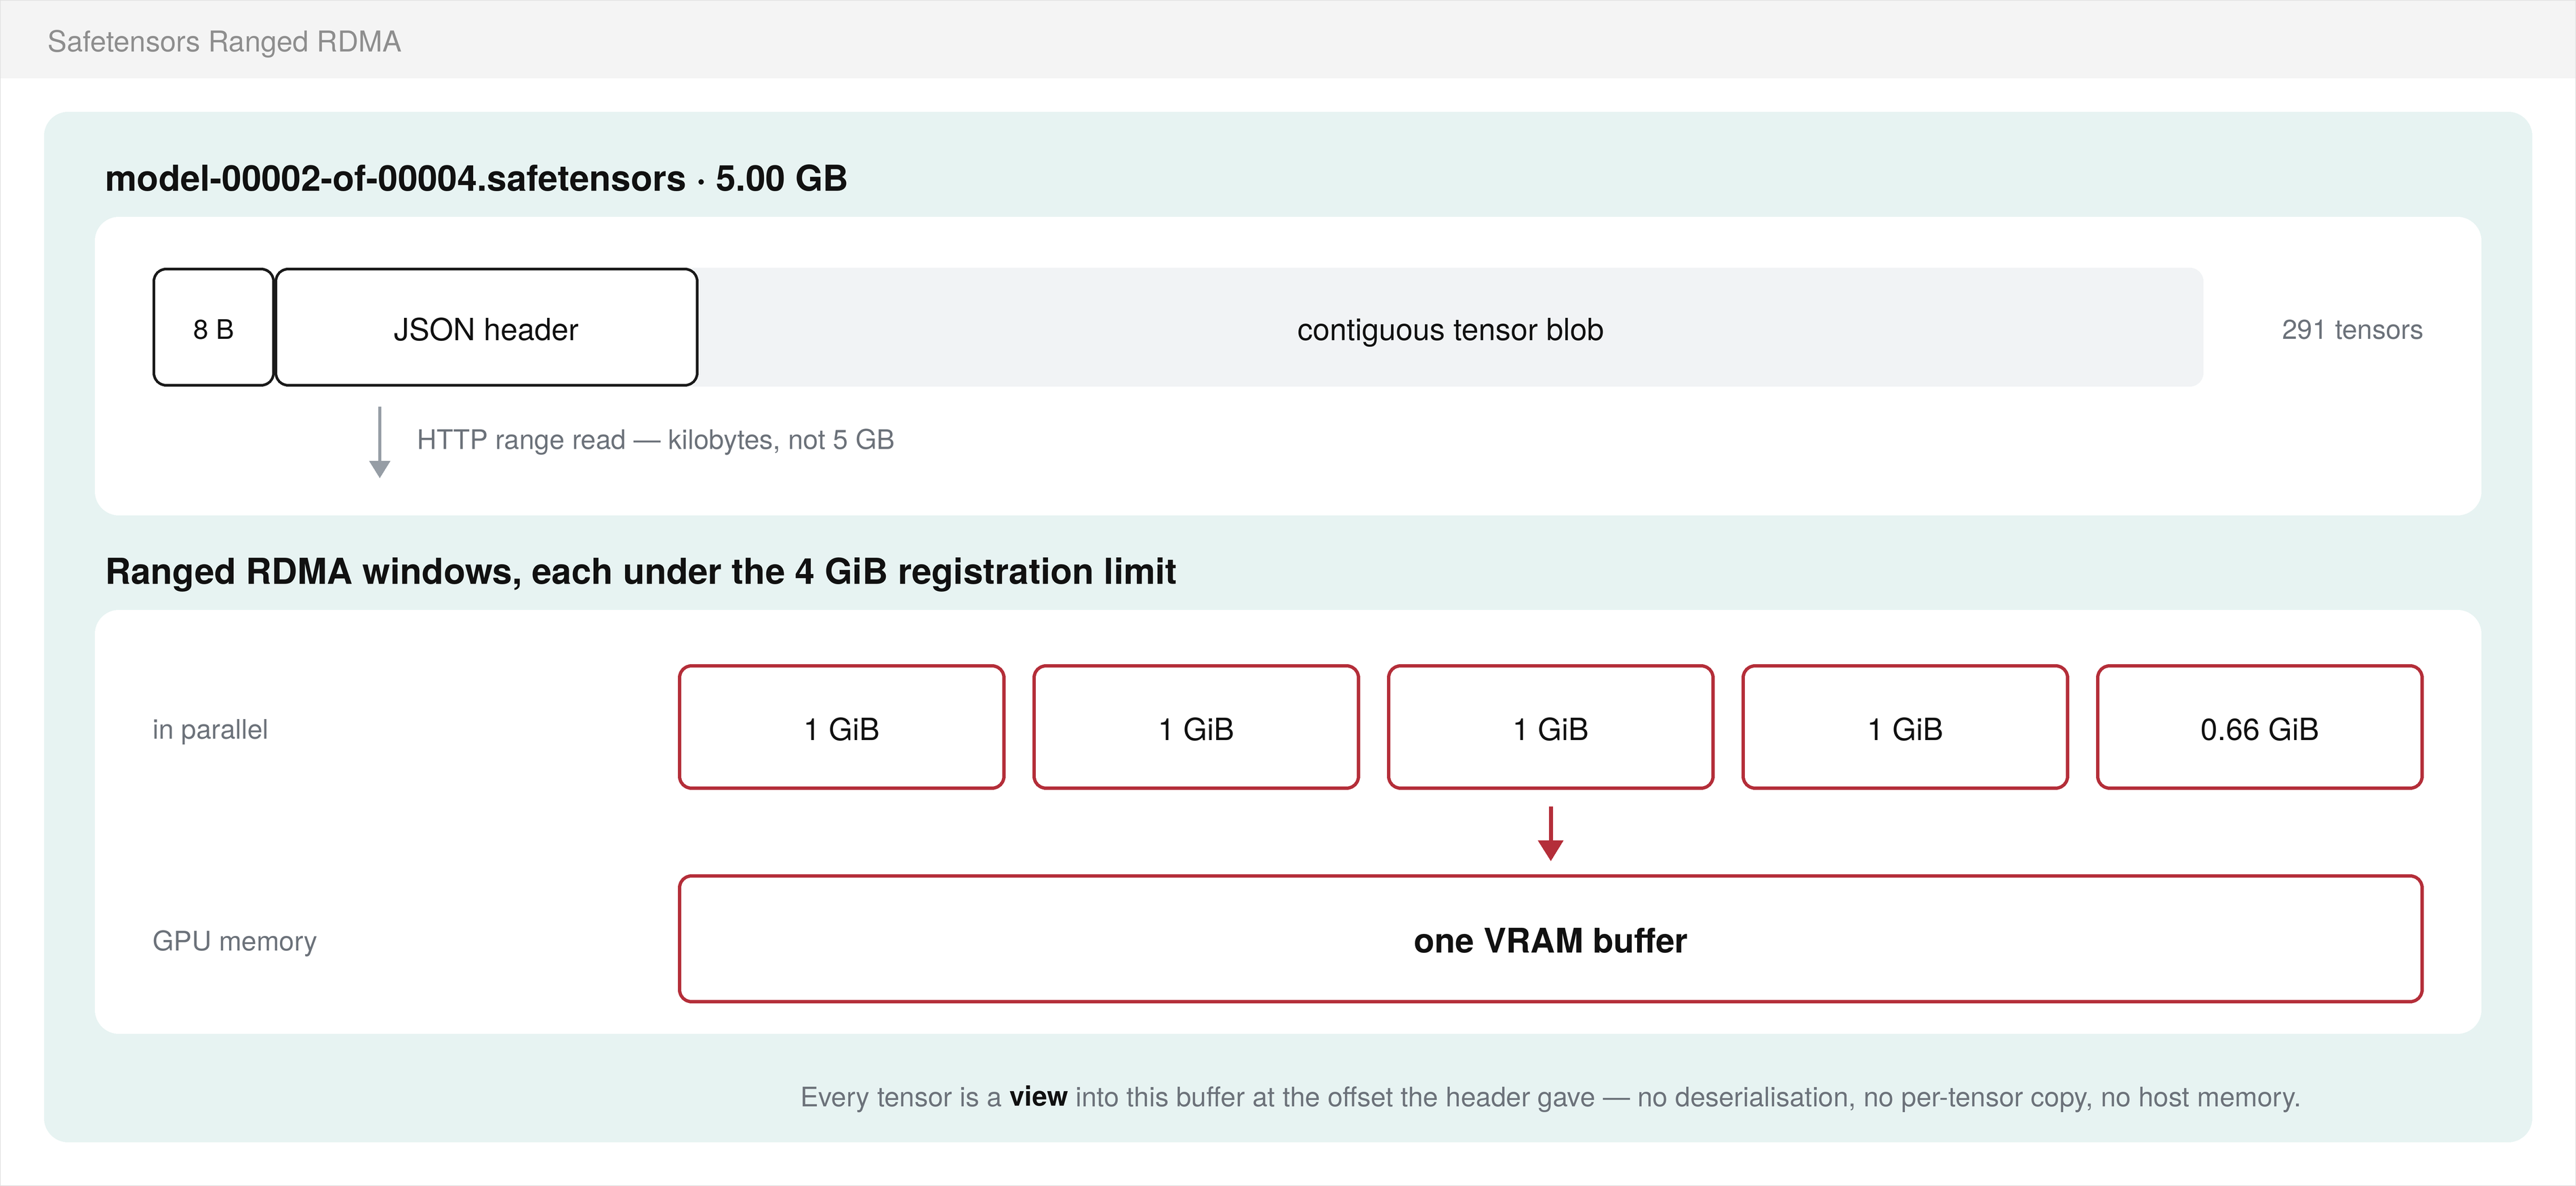
The same rule extends past the three headliners. Embedding and feature stores, pre-decoded image shards, tokenized corpora: anything whose bytes are already tensors takes the same path. We measured the three above; the mechanism does not change for the rest. NVIDIA, for its part, describes RDMA for S3-compatible storage as faster data access and performance for AI training and inference, including vector databases and key-value cache storage for inference in AI factories.
Of those, KV cache is the case we expect to grow fastest. The NVIDIA Dynamo inference framework separates prefill and decode into independently scaled worker pools, and its KV-aware routing selects workers on cache overlap and load, so prefill work that already exists is reused rather than recomputed. Cache blocks that outlive a session have to live somewhere, and the path that serves them back decides whether reuse costs less than recomputation. MinIO builds a dedicated product for that tier: MemKV, MinIO's context memory for AI inference, keeps KV cache blocks on flash and serves them back over RDMA with no filesystem and no object protocol in the path. S3 over RDMA is the path for everything that already lives in object storage, and that is where the rest of this post stays.
Tensors In, Tensors Out
One mental model tells you where S3 over RDMA applies: the GPU must be able to consume the bytes exactly as they sit in the bucket. RDMA delivers into GPU memory, so if the payload is tensors, raw arrays, safetensors, checkpoints, tokenized text, the GPU can use them the moment they land.
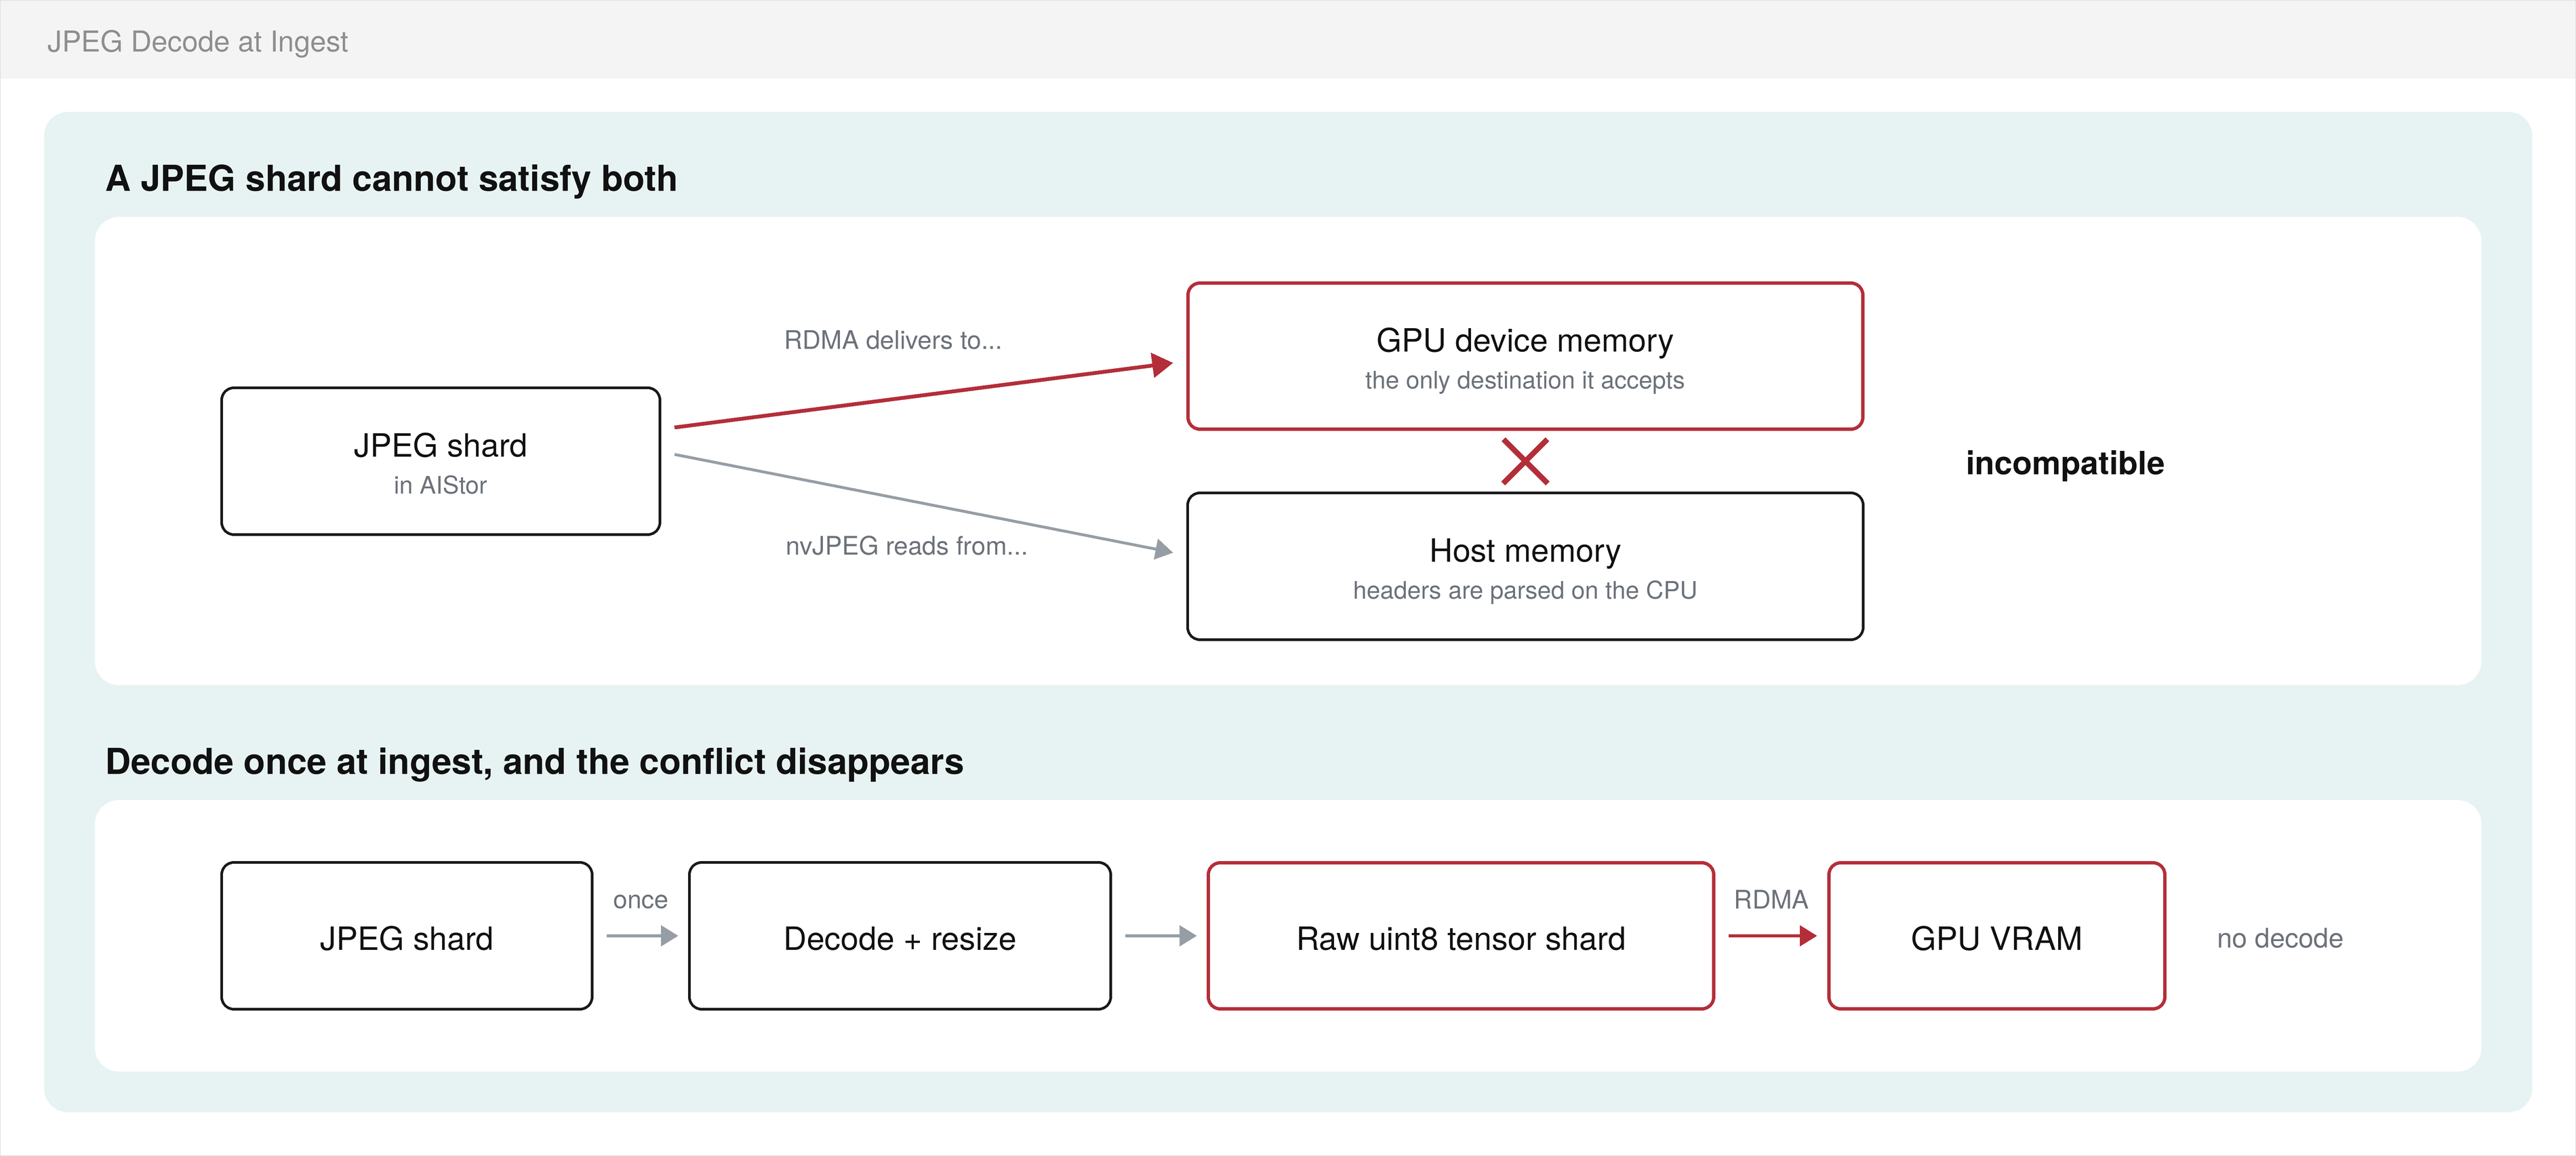
It equally tells you where it does not apply, and we would rather tell you now than have you find out in production. A JPEG dataset cannot use this path: GPU decoders need the encoded bitstream in host memory, so an image pipeline built on JPEGs keeps the host in the loop no matter the transport, the fix is pre-decoded shards, not a faster wire.
Where This Goes
The pattern here is an old one. GPUs got fast enough that copying became the bottleneck, so the copy had to go, first inside the box with NVIDIA GPUDirect, now across the fabric with RDMA for S3-compatible storage. Storage is simply the next thing to stop going through the CPU.
NVIDIA has described the same problem at platform scale. Inference-time scaling drives exponential growth in context and key-value cache size, and GPU memory limits cause severe slowdowns when that data has to move through standard storage channels. NVIDIA STX is a modular reference design for AI-native data platforms, positioned as the strategic data layer between massive compute and data, orchestrating data movement, access, and control to keep AI workloads continuously fed and highly utilized. NVIDIA STX is part of the NVIDIA Vera Rubin platform, combining the NVIDIA BlueField®-4 STX Storage Processor, NVIDIA DOCA™, and NVIDIA Spectrum-X Ethernet networking in a purpose-built architecture for AI-ready data. Its storage AI workloads include high-performance AI factory storage, NVIDIA CMX™ context memory storage to accelerate KV cache management for agentic AI and long-context reasoning, and enterprise AI data. Read that list with the last hop in mind. Every entry is a case where data must be ingested, processed, cached, or retrieved efficiently to keep GPUs productive. Wherever those bytes end in GPU memory, the last hop is the one this post is about.
The economics land in the same place. NVIDIA counts extreme co-design across compute, networking, storage and software among the strategies that raise energy efficiency, and treats available facility power as the primary limiting factor on throughput. Cores spent copying bytes are watts spent not producing tokens. Removing the copy is a performance result and an efficiency result at the same time.
The part we care most about: S3 over RDMA is generally available in AIStor, and you do not need a research cluster to reproduce this. The client side is one shared library and a small Python binding; the benchmarks in minio/rdma-training run on any AIStor tenant with an RDMA-capable fabric and the cuObject client from the NVIDIA CUDA Toolkit 13.1.1 or later, and the docs walk you from bare drives to a verified RDMA transfer, including every silent-fallback trap we hit so you don't have to. The numbers above came from the configuration described above, one 400 GbE RoCEv2 fabric feeding 8 GPUs. Your ceiling is set by the fabric you bring.
In the coming posts we will go hands-on with each workload: training on GPU-native shards, checkpointing at LLM scale, and cold-starting inference straight from the object store. If you have any questions, or a fabric you are wondering about, join our Slack community and ask!
Sources
- Grattafiori et al., The Llama 3 Herd of Models, Meta, 2024, arxiv.org/abs/2407.21783. 466 interruptions in a 54-day snapshot; ~78% of unexpected interruptions attributed to confirmed or suspected hardware issues; 16K H100s; storage sustaining 2 TB/s / 7 TB/s peak; checkpoint writes "highly bursty"; goal to "minimize GPU pause time during checkpointing and increase checkpoint frequency."
- Kokolis et al., Revisiting Reliability in Large-Scale Machine Learning Research Clusters, Meta, 2024, arxiv.org/abs/2410.21680. MTTF 7.9 h at 1,024 GPUs, projected 1.8 h at 16,384 and 0.23 h at 131,072; hourly checkpointing typical for larger jobs; average half an hour of lost work.
- Eisenman et al., Check-N-Run: A Checkpointing System for Training Deep Learning Recommendation Models, Facebook, NSDI 2022, arxiv.org/abs/2010.08679. "Checkpoint frequency is often bottlenecked by the storage write bandwidth and capacity."
- Wan et al., ByteCheckpoint: A Unified Checkpointing System for Large Foundation Model Development, ByteDance, 2024, arxiv.org/abs/2407.20143. Runtime checkpoint stalls reduced by an average of 54.2× versus existing open-source systems.
- Fu et al., ServerlessLLM: Low-Latency Serverless Inference for Large Language Models, OSDI 2024, arxiv.org/abs/2401.14351. Checkpoint download/loading as the dominant cold-start cost; 10–200× latency reduction.
- NVIDIA, How to Unlock Accelerated AI Storage Performance With RDMA for S3-Compatible Storage, NVIDIA Blog, November 14, 2025, blogs.nvidia.com/blog/s3-compatible-ai-storage. Capability naming, client and server library model, reduced CPU utilization, workload portability, stated use cases for training and inference, open architecture, standardization with storage partners.
- NVIDIA, NVIDIA cuObject: GPUDirect Storage for Objects, NVIDIA GPUDirect Storage documentation, docs.nvidia.com/gpudirect-storage/cuobject. Client and server library roles, control and data plane split, x-amz-rdma-token, Dynamic Connection transport over InfiniBand and RoCEv2, client library in CUDA Toolkit 13.1.1 and later.
- NVIDIA, NVIDIA Dynamo: Disaggregated Serving, NVIDIA Dynamo documentation, docs.dynamo.nvidia.com. Prefill and decode disaggregation, KV-aware routing on cache overlap and load.
- NVIDIA, NVIDIA STX Solution Overview, July 2026, nvidia.com/stx. STX positioning as the strategic data layer, storage AI workloads, Vera Rubin, BlueField-4, DOCA, CMX, Spectrum-X.
- All MinIO figures: github.com/minio/rdma-training, code, docs, and raw JSON for all 146 runs, each RDMA figure carrying a server-side counter delta.